What Is a Cluster? Definition, How It Works, and Use Cases

- Level
- Beginner
- Reading time
- 18 min
- Concept
- Computer cluster
- Last reviewed
- July 4, 2026
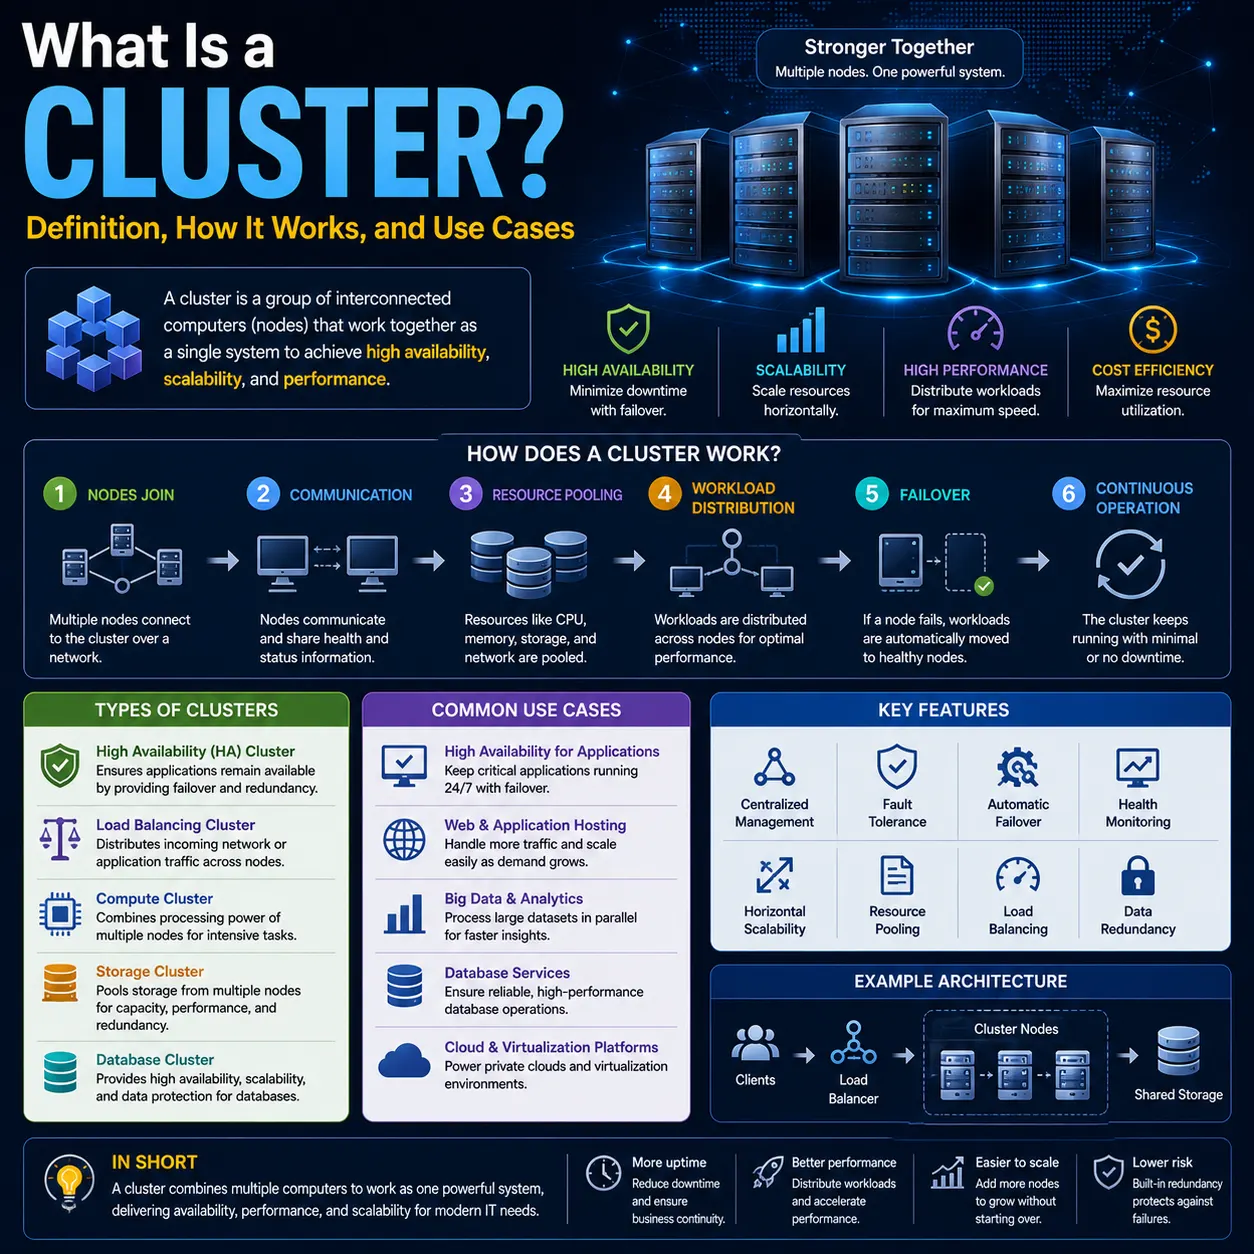
Table of contents
A cluster is a group of interconnected computers that work together as a single system. Instead of relying on one server - which becomes a bottleneck and a single point of failure - a cluster spreads work and redundancy across multiple nodes, so the service keeps running when a node fails and can scale as demand grows. Clusters power everything from a small business's high-availability database to the massive systems behind search engines and streaming platforms. The catch is that coordinating independent computers safely requires mechanisms most people never see: heartbeats, quorum voting, and fencing.
Key takeaways
- A cluster makes multiple nodes act as one system for availability, performance, or scale.
- Main types: high-availability/failover, load-balancing, HPC/compute, and storage clusters.
- Nodes exchange heartbeats; on failure, work fails over to healthy nodes.
- Quorum (majority voting) plus fencing/STONITH prevent split-brain data corruption.
- A cluster provides availability, not backup - you still need backups and DR.
Quick explanation
In simple terms
Several computers connected to work as one, so if one breaks the others keep the service running.
Technical definition
A set of interconnected nodes coordinated by clustering software providing membership, quorum, resource management, and fencing, presenting a unified, fault-tolerant, or scalable computing resource.
Analogy
A cluster is like a relay team: members share the race and can cover for a runner who drops out - but they need clear rules (quorum and fencing) so two runners never grab the same baton at once.
Definition
A cluster is a group of two or more interconnected computers (nodes) configured to work together as a single system, so they can deliver higher availability, performance, or scalability than any one machine alone.
A cluster is a collection of independent computers, called nodes, that are interconnected over a network and coordinated by clustering software so they appear to users and applications as one unified resource. Nodes exchange heartbeat signals to monitor each other's health and share workloads, data, and services. Clusters differ from ordinary networked computers because they're purpose-built for coordination and redundancy: if a node fails, others take over its work. To keep data safe when the network splits, clusters rely on quorum (majority voting) and fencing to ensure only one group of nodes ever acts on shared data.
Why it matters
Core concepts
Nodes and the single-system illusion
A cluster is built from nodes that appear to users as one system.
Each node is an independent computer contributing CPU, memory, and storage. Clustering software coordinates them so users and applications interact with the cluster as a single, more capable resource - a single-system image for the services it presents. This coordination, not just the network link, is what makes a cluster more than a group of networked PCs.
Example
Three web servers behind one virtual IP appear to users as a single, always-available site.
Why it matters — The single-system illusion is the value of clustering: complexity is hidden while resilience and scale are gained.
Types of clusters
Clusters are optimized for availability, load, computation, or storage.
There are four common types. High-availability (failover) clusters keep a service running by moving it to a healthy node on failure (often active/passive). Load-balancing clusters spread incoming requests across many active nodes for throughput. High-performance computing (HPC/compute) clusters combine many processors to solve one large problem in parallel. Storage (distributed) clusters pool disks across nodes for shared, resilient storage. Many real systems blend types - e.g., a load-balanced, highly available web tier.
Example
A bank runs an HA failover cluster for its database and a load-balancing cluster for its web front end.
Why it matters — Choosing the right type (or blend) is the first design decision and drives the whole architecture.
Heartbeat and health monitoring
Nodes continuously signal their health so failures are detected fast.
Nodes exchange heartbeat messages (ideally over redundant, independent paths) so the cluster knows which nodes are alive. Continuous monitoring tracks node status and resource health; missed heartbeats trigger the cluster's failure response. Redundant heartbeat paths reduce false failure detection and help avoid split-brain.
Example
When node B stops sending heartbeats, the cluster flags it as failed and begins recovery.
Why it matters — Reliable failure detection is the trigger for every recovery action; false positives cause needless failovers.
Failover and high availability
Services move from a failed node to a healthy one with minimal disruption.
When a node fails, the cluster fails over its services and data access to surviving nodes, usually via shared or replicated storage so the data is still reachable. Advanced clusters also do rolling updates, upgrading nodes one at a time while the service stays up. Failover reduces downtime but isn't instantaneous - there's a brief interruption while services restart elsewhere.
Example
A database's virtual IP and storage move to the standby node; clients reconnect within seconds.
Why it matters — Failover is the mechanism behind 'high availability' - the core reason many clusters exist.
Quorum (preventing split-brain)
A cluster has quorum when a majority of nodes (or votes) can communicate.
If the network splits, each side might think the other is dead and both could act on shared data - a split-brain that corrupts data. Quorum solves this: only the partition holding a majority of votes is allowed to run services. In a 6-node cluster, quorum needs at least 4 online. Odd node counts avoid ties; for two-node or even clusters, a witness / quorum device (tiebreaker) supplies an extra vote so exactly one side wins.
Example
In a 3-node cluster split 2-versus-1, the 2-node side keeps quorum and runs; the lone node stands down.
Why it matters — Quorum is what guarantees only one partition ever writes to shared data - the foundation of cluster safety.
Fencing (STONITH)
Forcibly isolating a suspect node so it can't corrupt shared data.
Quorum decides who should run; fencing enforces it by isolating or powering off a node that may still be alive but out of contact. The common implementation is STONITH ('Shoot The Other Node In The Head'). Because a 'dead' node's true state is unknown, fencing guarantees it can't keep writing before services move. Methods include power switches (PDU), out-of-band controllers (IPMI/iLO), storage-based death (SBD), or hypervisor APIs. Without fencing, data integrity can't be guaranteed for stateful services.
Example
A node that lost network but might still hold storage is power-cycled via IPMI before failover proceeds.
Why it matters — Fencing is the safety net that makes failover trustworthy for databases and other stateful workloads.
How it works
Interconnect nodes and start heartbeats
Nodes are linked over high-speed networks (Ethernet/InfiniBand), ideally with redundant paths, and begin exchanging heartbeat signals.
Interconnect + heartbeat
Example — Two nodes exchange heartbeats over two independent NICs.
Cluster software coordinates membership and resources
Clustering software (e.g., Pacemaker/Corosync, Microsoft Failover Clustering, Kubernetes) tracks which nodes are members and manages services/resources.
Coordinate
Example — Corosync maintains membership; Pacemaker manages resources.
Distribute work or run services
Requests or tasks are distributed across active nodes (load-balancing/HPC), or a service runs active/passive with data on shared storage (HA).
Distribute / run
Example — A load balancer spreads web requests across nodes.
Detect failure via missed heartbeats
When a node stops responding, monitoring flags it as failed and the cluster prepares to recover its workload.
Detect failure
Example — Node B misses several heartbeats and is marked down.
Resolve with quorum, then fence
Quorum determines which partition may run; fencing (STONITH) isolates the suspect node so it can't touch shared data.
Quorum + fence
Example — The majority partition keeps quorum and fences the lost node via IPMI.
Fail over and restore service
Services and data access move to healthy nodes; users reconnect with minimal disruption, and the failed node can rejoin later.
Failover
Example — The database restarts on the standby node within seconds.
Use cases
High-availability business applications
IT ops, businessKeep e-commerce, banking, and critical apps online through node failures with automatic failover.
A retailer's checkout stays up when a web node fails during a sale.
Benefit — Continuous availability
Scientific and high-performance computing
Research/engineeringCombine many processors to run large parallel computations.
A weather service runs forecast models across an HPC cluster.
Benefit — Massive parallel throughput
Database clusters
DBAsProvide availability and performance for databases via replication and failover.
A PostgreSQL or SQL Server failover cluster protects transaction processing.
Benefit — Data availability and performance
Container orchestration (Kubernetes)
DevOps/platform teamsRun and self-heal containerized microservices across many nodes, scaling on demand.
Kubernetes reschedules pods from a failed node automatically.
Benefit — Self-healing, elastic scaling
Content delivery and streaming
Media/platform teamsScale to demand spikes and cache content close to users.
A streaming service absorbs a viewing spike across clustered edge nodes.
Benefit — Smooth delivery at scale
Benefits
High availability
Automatic failover keeps services running when individual nodes fail.
A node crash doesn't take the service offline.
Scalability
Add nodes to grow capacity without taking the service down.
Scale out for a traffic surge.
Performance
Distributing work across machines improves throughput and response times.
Parallel processing shortens a batch job.
Cost efficiency
Commodity hardware in a cluster often beats an equivalent high-end single server.
Several mid-range servers instead of one large one.
Geographic distribution and DR
Stretch or replicate across sites for disaster recovery and lower latency.
A stretched cluster survives a data-center outage.
Limitations
Split-brain risk if failure handling is wrong
HighA network partition can let two sides act on shared data and corrupt it if quorum and fencing aren't correct.
Workaround — Use majority quorum with an odd node count or a witness/quorum device, and configure fencing (STONITH) for all stateful resources.
Complexity
MediumDesign, configuration, and troubleshooting require specialized skills; mistakes cause outages.
Workaround — Standardize designs, use config management (Ansible/Puppet), and test failover regularly.
Network dependency
MediumCluster health depends on reliable, low-latency links; a flaky interconnect triggers false failovers.
Workaround — Provide redundant, independent heartbeat paths with no single point of failure.
Cost and per-node licensing
MediumMultiple servers, networking, and shared storage add cost, and some software licenses per node.
Workaround — Right-size the cluster, consider commodity hardware, and check licensing models before scaling out.
Resource and operational overhead
LowCluster software and inter-node coordination consume resources and add operational tasks.
Workaround — Budget capacity for overhead and invest in monitoring and runbooks.
Architecture
A cluster combines nodes, a (preferably redundant) interconnect for data and heartbeats, clustering software that manages membership/quorum/resources, shared or replicated storage for stateful services, a quorum witness for tiebreaking, and a fencing device to isolate failed nodes. A virtual IP or load balancer presents the cluster as one endpoint.
Nodes
Independent computers providing compute, memory, and storage
Three servers or VMs
Interconnect / heartbeat network
Carries data and health signals, ideally over redundant paths
Dual NICs or InfiniBand
Clustering software
Manages membership, quorum, resources, and fencing
Pacemaker/Corosync, MS Failover Clustering, Kubernetes
Shared / replicated storage
Keeps data reachable across nodes for failover
SAN, NAS, or DRBD replication
Quorum witness / tiebreaker
Supplies an extra vote so exactly one partition wins
QDevice/QNetd or a witness disk/share
Fencing device
Isolates or powers off a suspect node (STONITH)
IPMI/iLO, PDU, or SBD
Data flow
Nodes heartbeat over the interconnect then clustering software tracks membership and resource health; work is distributed or a service runs active/passive on shared storage; on failure, quorum selects the surviving majority and fencing isolates the failed node; services fail over and clients reconnect.
Integrations: Pacemaker/Corosync (Linux HA), Microsoft Failover Clustering (Windows Server), Kubernetes (container orchestration), Monitoring (Prometheus) and config management (Ansible)
Architecture limitations
Examples
Two-node database failover cluster
A database must survive a server failure without data corruption.
An active/passive cluster shares storage; because two nodes can't form a majority, a witness provides a tiebreaker vote and fencing power-cycles a lost node before failover.
Kubernetes self-healing
A node running several microservice pods fails.
The Kubernetes control plane detects the node as unhealthy and reschedules its pods onto healthy nodes, keeping the application available.
Comparisons
High-availability cluster vs load-balancing cluster vs Load-balancing cluster
An HA (failover) cluster focuses on keeping a service running through failures, often active/passive; a load-balancing cluster focuses on throughput by spreading requests across many active nodes. They're often combined.
| Criterion | High-availability cluster vs load-balancing cluster | Load-balancing cluster |
|---|---|---|
| Primary goal | Availability (survive failures) | Throughput (handle load) |
| Node usage | Often active/passive | All nodes active |
| Key mechanism | Failover + quorum + fencing | Request distribution across nodes |
When to choose — Use HA for stateful services that must survive failures; use load balancing for scaling stateless request handling - and combine them for a resilient, scalable tier.
Cluster vs managed cloud service vs Managed cloud service
A self-run cluster gives full control and dedicated performance but demands expertise and investment; a managed cloud service abstracts the cluster, trading control for lower operational burden and pay-per-use scaling.
| Criterion | Cluster vs managed cloud service | Managed cloud service |
|---|---|---|
| Control | Full control of hardware/config | Provider-managed abstraction |
| Scaling | Limited by owned capacity | On-demand, near-unlimited |
| Operational burden | High (you run it) | Low (provider runs it) |
| Cost model | Higher upfront, lower ongoing | Low upfront, pay-per-use |
When to choose — Run your own cluster when you need control, dedicated performance, or on-prem placement; use managed cloud (e.g., managed Kubernetes) to offload operations and scale elastically.
Myths, corrected
Myth
A cluster is a backup or disaster-recovery solution.
Correction
High availability protects against node failure, not against data loss, corruption, ransomware, or accidental deletion - those replicate instantly to shared storage. You still need backups and a DR plan alongside a cluster.
Why it happens: 'Redundancy' is read as 'my data is safe,' conflating availability with data protection.
Myth
A cluster and cloud computing are the same thing.
Correction
They're related but different. A cluster is the underlying technology of multiple computers working together; cloud services often run on clusters but add self-service, automatic scaling, and pay-per-use on top.
Why it happens: Cloud platforms hide the cluster, so the terms blur together.
Myth
More nodes always means more reliable.
Correction
Beyond a point, adding nodes adds complexity, cost, and coordination overhead. What matters for safety is correct quorum (an odd count or a witness) and fencing - not raw node count. An even number of nodes without a witness can even reduce safety.
Why it happens: 'More redundancy = better' is intuitive but ignores quorum math.
Myth
A cluster eliminates all downtime.
Correction
Clusters reduce downtime, they don't eliminate it. Failover causes a brief interruption while services restart, and a misconfigured cluster (bad quorum/fencing) can itself cause outages or data corruption.
Why it happens: 'High availability' is heard as 'zero downtime,' which oversells what failover delivers.
Practical implications
For admins
Design quorum (odd count or witness) and configure fencing for all stateful resources; use redundant heartbeat paths; test failover and fencing regularly.
For MSPs
Standardize HA cluster designs across clients, document quorum/fencing setups, and monitor for split-brain conditions and false failovers.
For business
Clusters buy uptime and scale but require investment and expertise; pair them with backups and DR, and weigh managed cloud alternatives.
For security
Encrypt inter-node communication (TLS/IPsec), authenticate cluster management, isolate cluster traffic, and patch cluster software promptly.
For end users
Impact is indirect: services that stay online and perform well, usually without users noticing a node failure.
Cost impact
Multiple nodes, networking, shared storage, and possible per-node licensing raise cost; commodity hardware and right-sizing help control it.
Operational impact
Introduces HA operations - membership, quorum, fencing, rolling updates, and DR testing - that need skills, runbooks, and change control.
Decision guide
Use when
- A service must stay available through hardware or node failures
- You need to scale capacity beyond a single server
- You run compute-heavy or high-transaction workloads
Avoid when
- A single server (plus backups) meets your availability needs
- You lack the expertise or budget to run failure handling correctly
- A managed cloud/PaaS already provides the resilience you need
Requirements
- At least two nodes (three or more for majority quorum)
- A reliable, ideally redundant interconnect
- Shared or replicated storage for stateful services, plus fencing
Alternatives
- A single robust server with solid backups
- Managed cloud services (e.g., managed Kubernetes, managed databases)
- A load balancer alone for stateless scaling
Related terms
Node
An individual computer that is a member of a cluster.
Failover
Moving a service from a failed node to a healthy one.
Quorum
The majority of nodes/votes required for a partition to run safely.
Split-brain
A partition where both sides act on shared data, risking corruption.
Fencing / STONITH
Isolating or powering off a suspect node to protect shared data.
Witness / quorum device
A tiebreaker vote for two-node or even-numbered clusters.
Frequently asked questions
What is a cluster in simple terms?
A cluster is a group of computers connected to work as one system. Like a team, if one computer fails the others keep working, so applications stay running and can handle more load.
What is a cluster used for?
Making services more reliable and scalable - high-availability web and business apps, databases, scientific/HPC computing, container orchestration (Kubernetes), and content delivery.
Is a cluster the same as cloud computing?
No, but they're related. A cluster is the underlying technology of multiple computers working together; cloud computing often runs on clusters but adds self-service, automatic scaling, and pay-per-use on top.
How many computers do you need for a cluster?
At least two, but most production high-availability clusters use three or more so a majority (quorum) can be formed. Two-node clusters need a witness/quorum device and fencing to stay safe.
What happens when a node fails?
The cluster detects missed heartbeats, uses quorum to decide which partition may run, fences (isolates) the failed node so it can't corrupt shared data, and fails over its services to healthy nodes - usually with only a brief interruption.
Is a cluster a backup?
No. A cluster provides availability, not backup. Data loss, corruption, ransomware, or accidental deletion replicate to shared storage instantly, so you still need separate backups and a disaster-recovery plan.
What's the difference between a cluster and a load balancer?
A load balancer distributes requests across servers for throughput; a high-availability cluster keeps a service running through failures using failover, quorum, and fencing. Load balancing is often one part of a larger cluster design.
Conclusion
A cluster is a group of interconnected nodes coordinated by software to act as one system, delivering high availability, performance, or scale. Nodes heartbeat and share work; on failure, quorum selects the surviving majority and fencing (STONITH) isolates the lost node before services fail over - with a witness providing a tiebreaker for two-node or even clusters. Main types are high-availability, load-balancing, HPC, and storage.
Main takeaway
Read an explainer on high availability or Kubernetes for depth, or a tutorial on building a Pacemaker/Corosync or Failover Clustering setup for hands-on practice.