When a project grows past one developer - or one laptop - the hard questions start: what changed, who changed it, and how do you get back to a state that worked? Git answers those questions by giving every developer a complete copy of the project history, enabling offline work, parallel development and painless recovery from mistakes. This explainer covers how its snapshot model works, where it fits in your workflow, and when another tool is the better choice.
Key takeaways
- Every clone is a full backup: any developer's machine can restore the complete project history.
- History is a chain of snapshots, so any past state can be compared, reverted or restored in seconds.
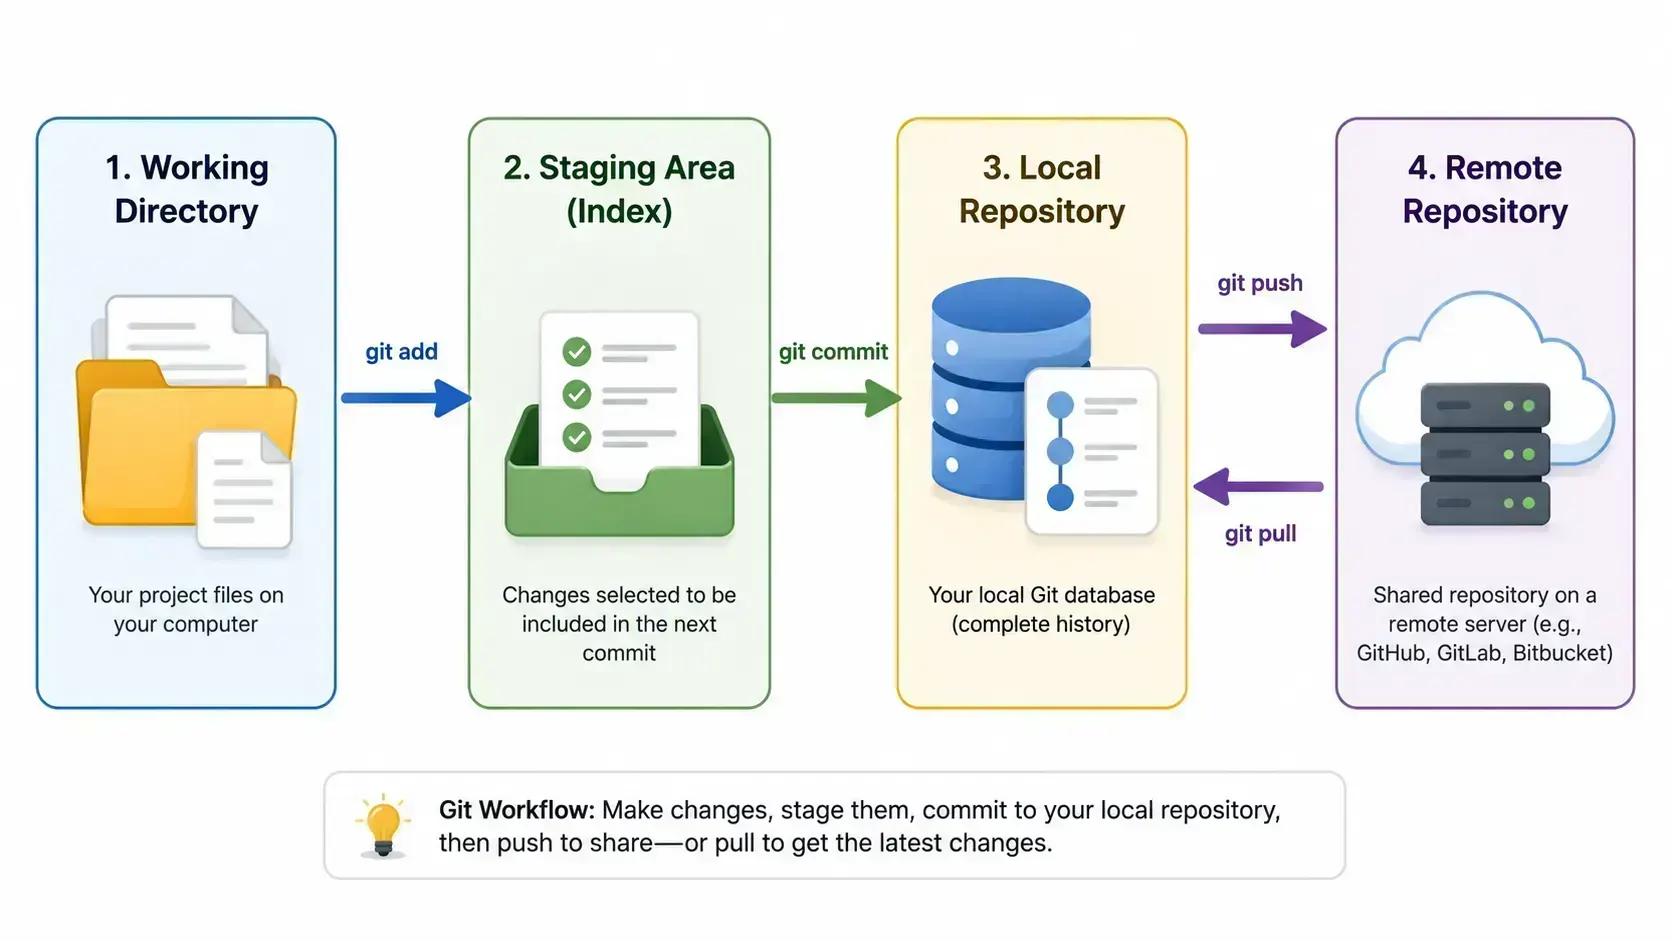
- The core workflow moves changes from working directory to staging area to repository to remote.
- Git is not GitHub - Git is the tool, GitHub is a hosting platform built around it.
Definition
Clean article cover illustration showing the Git logo, commit history branches, code on a laptop, project files, hashes, and collaboration icons.
Git is a distributed version control system created by Linus Torvalds in 2005 for Linux kernel development. It records the state of a set of files as a series of snapshots (commits), each identified by a cryptographic hash. Its distributed design - explored in the concepts below - is what set it apart from the centralized tools it replaced.
Why it matters
Core concepts
Repository
A repository (repo) is the full collection of a project's files plus its complete change history.
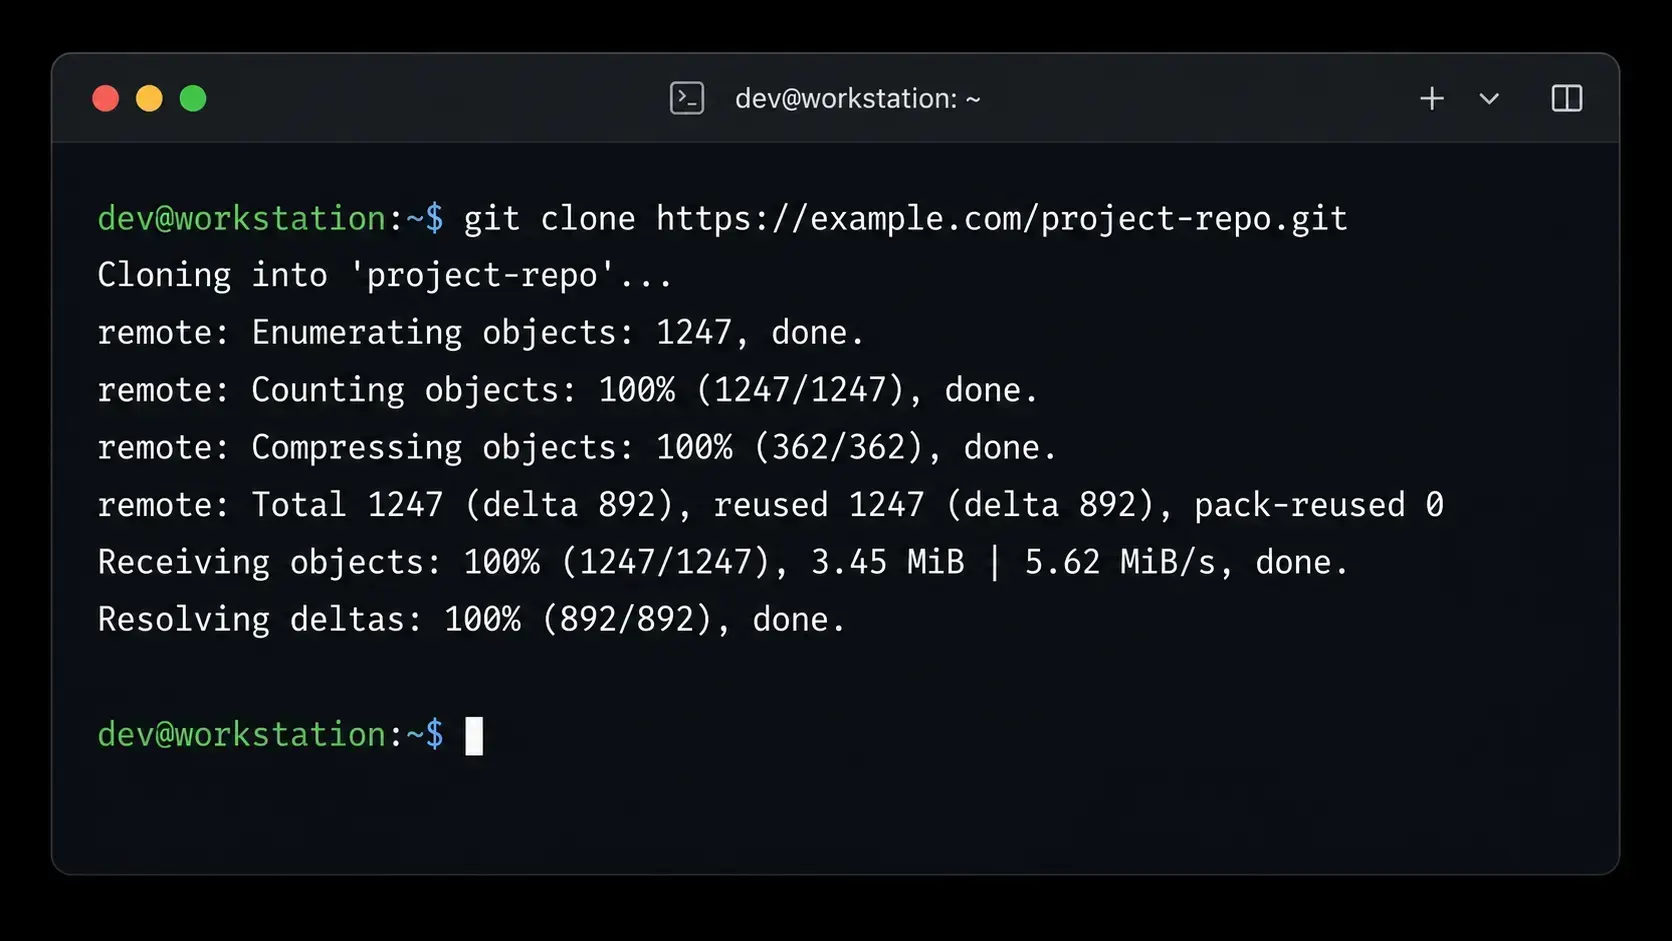
When you clone a repository you receive not just the latest files but every commit, branch and tag ever created. A local repository lives on your machine; a remote repository is a shared copy that team members synchronize with.
Example
Cloning a project with git clone downloads the entire history, not just the current state.
Why it matters — Everything Git knows - commits, branches, tags - lives in the hidden .git folder inside the repo, so archiving or moving a project is as simple as copying that one directory.
Commit
A commit is a permanent snapshot of the staged project state, identified by a unique cryptographic hash.
Each commit records the complete state of tracked files at a point in time along with metadata such as author, timestamp and message. Commits form a linked history that Git can traverse, compare and revert.
For a deeper look at hashes, parents and trees, see What is a commit in Git.
Example
git commit -m "Fix user authentication bug in login module" saves staged changes as a new snapshot.
Why it matters — Commits are the atomic units of history - clear, focused commits make it easy to trace bugs and understand how a project evolved.
Branch
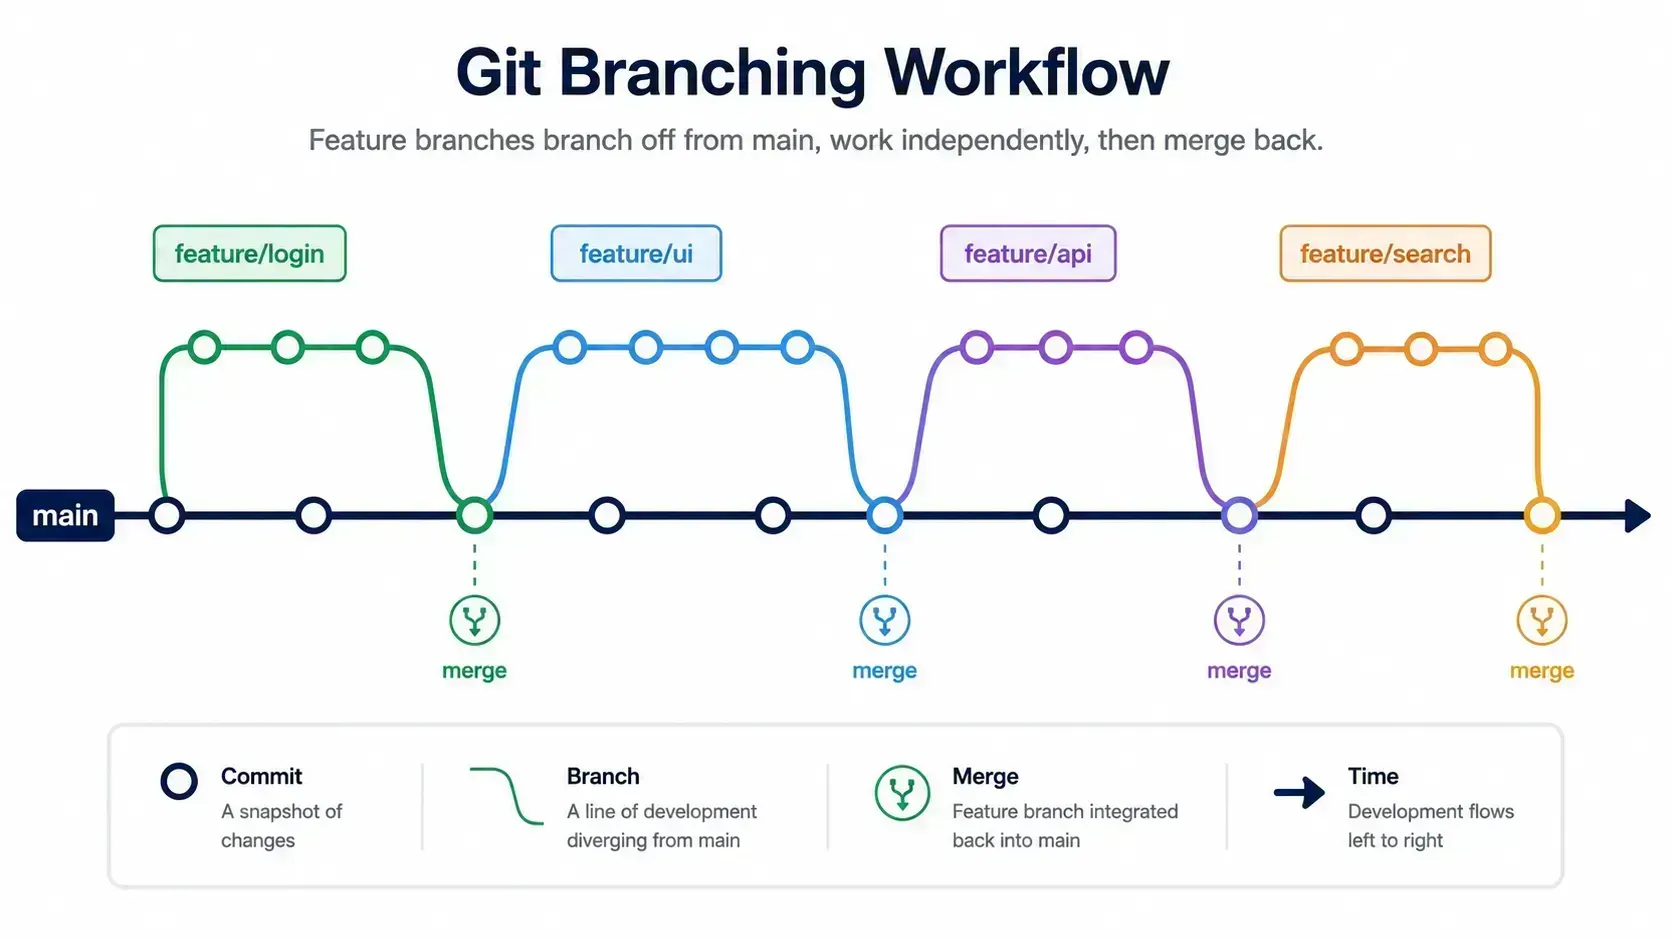
A branch is a lightweight, movable pointer to a line of commits, used to develop work in isolation.
Git branches are cheap to create and switch between, which encourages isolating features, fixes or experiments before merging them back into the main line. This is a defining strength of Git compared to older systems.
Example
Creating a feature branch to build new functionality without disturbing the main branch.
Why it matters — Lightweight branching enables parallel development and code review workflows like Git Flow and GitHub Flow.
Staging area (index)
The staging area is where you select which changes will be included in the next commit.
Editing files in the working directory does not automatically record them. You use git add to move specific changes into the staging area, then git commit to save that selection as a snapshot. This lets you craft focused commits.
Example
Staging only the files relevant to a bug fix while leaving unrelated edits out of the commit.
Why it matters — The staging step gives fine-grained control over what each commit contains, improving history quality.
Distributed architecture
Every clone is a complete, independent repository rather than a thin checkout of a central server.
In a distributed model, most operations run locally and require no network. Developers can commit, branch, and inspect history offline, then synchronize with remotes when convenient.
Example
Committing work on a plane with no connectivity, then pushing later.
Why it matters — It removes single points of failure and makes local operations fast.
How it works
Edit files in the working directory
The working directory is your local folder where you edit files. Git monitors this directory for changes but does not automatically track them until you tell it to.
Working directory
Example — Modifying a source file in your project folder.
Stage changes with git add
When you are ready to save changes, you add them to the staging area (index) using git add. This is like preparing items for shipment - you select which changes to include in your next snapshot.
Staging area
Example — git add login.js to stage a single file.
Commit to the local repository
The staging area contents are permanently saved to the repository with git commit. From here the change is part of history: you can branch from it, compare against it, or revert to it.
Local repository
Example — git commit -m "Add password validation".
Synchronize with a remote
Your local repository can synchronize with remote repositories using git push (upload) and git pull (download), sharing commits with teammates.
Remote repository
Example — git push origin main to publish local commits.
Use cases
Source code management
Software development teamsGit's primary use case is tracking changes in source code across programming languages, letting development teams coordinate work on applications, websites and system software.
Multiple developers work on different features simultaneously, with Git merging their changes together.
Benefit — Parallel development without overwriting each other's work.
Documentation and content management
Technical writers and content teamsTechnical writers use Git for documentation projects, leveraging branching and merging to manage complex content workflows.
Documentation sites built with Jekyll or Hugo, or platforms like GitBook, storing content in Git.
Benefit — Versioned, collaborative documentation with review workflows.
Configuration and infrastructure-as-code
Sysadmins and DevOps engineersSystem administrators version-control configuration files, deployment scripts and infrastructure definitions in Git.
Ansible playbooks, Terraform configurations and Kubernetes manifests stored in Git repositories.
Benefit — Infrastructure changes tracked with the same rigor as application code.
Research and data science
Researchers and data scientistsResearchers and data scientists track changes in datasets, analysis scripts and papers, using Git LFS to handle large binary files.
Managing machine learning models and datasets with Git LFS.
Benefit — Reproducible research with tracked history.
Legal and compliance documentation
Legal and compliance teamsOrganizations maintain audit trails for legal documents, compliance procedures and regulatory filings using Git's immutable history and cryptographic integrity.
Tracking every change to a compliance procedure with accountability.
Benefit — Detailed, tamper-evident change tracking for accountability.
Benefits
Distributed architecture
No infrastructure dependency: a failed server or stolen laptop costs at most the commits that were never pushed.
Any developer's clone can re-seed a brand-new remote in minutes.
Lightweight branching and merging
Git's fast, cheap branching enables parallel development workflows and experimentation.
Creating a feature branch for each new task and merging via pull requests.
Fast local performance
Most commands run locally without network access, making common operations fast.
Viewing history or committing works instantly offline.
Data integrity
Cryptographic hashing ensures data corruption is detectable across every object.
Each commit, tree and blob has a unique hash that would change if the content were altered.
Industry standard tooling
Widespread adoption means extensive tooling, hosting options and community support.
Broad ecosystem support across GitHub, GitLab and Bitbucket.
Limitations
Steep learning curve
MediumGit's powerful feature set can be overwhelming for beginners.
Workaround — Start with add, commit and push, then gradually learn branching, rebasing and cherry-picking.
Poor handling of large binary files
MediumGit struggles with large binary files without extensions.
Workaround — Use Git LFS (Large File Storage) for large binaries, models and datasets.
Confusing history if mismanaged
LowPoorly managed repositories can develop tangled, hard-to-read commit histories.
Workaround — Adopt commit conventions and branching strategies like Git Flow or GitHub Flow.
Storage overhead
LowComplete history replication can consume significant disk space for large projects.
Workaround — Use shallow clones or Git LFS where full history or large assets are not needed locally.
Manual merge conflict resolution
MediumResolving conflicts between competing changes requires manual intervention and expertise.
Workaround — Commit early and often, keep branches short-lived, and pull frequently to reduce divergence.
Architecture
Beyond the day-to-day workflow, Git's design is worth a look: it is a content-addressed object database with a graph on top. That model explains why some operations feel instant while others - like removing data from history - are genuinely hard.
Data flow
Under the hood, every commit points to a tree (the full directory snapshot) and to its parent commit, forming a directed acyclic graph. Branches and tags are just named pointers into that graph - which is why creating a branch is instant and why history can be traversed, compared and merged so cheaply.
Integrations: Hosting platforms (GitHub, GitLab, Bitbucket), CI/CD pipelines, Git LFS for large binary files, Git hooks for automation
Architecture limitations
Examples
Recovering a deleted local repository
A developer accidentally deletes their local project folder.
The developer clones the repository from the remote again. Everything up to the last push comes back - commits, branches and tags. The only work to redo is whatever had never been pushed.
Parallel feature development
Five developers work on a critical project at the same time.
Each developer creates a feature branch to work in isolation, then opens a pull request to merge changes back. Git tracks who changed what and handles combining the work, avoiding overwritten changes and lost files.
Comparisons
Git vs Subversion (SVN)
Git is distributed and works fully offline with lightweight branching, while SVN is centralized and requires server connectivity for most operations.
| Criterion | Git | Subversion (SVN) |
|---|---|---|
| Architecture | Distributed | Centralized |
| Offline work | Full functionality | Limited |
| Branching | Lightweight, fast | Heavy, slow |
| Learning curve | Steep | Moderate |
When to choose — Git for most modern collaborative development; SVN mainly appears in legacy systems.
Git vs Mercurial
Both are distributed version control systems. Mercurial offers similar benefits with a gentler learning curve, but Git's ecosystem and tooling have made it the market leader.
| Criterion | Git | Mercurial |
|---|---|---|
| Architecture | Distributed | Distributed |
| Offline work | Full functionality | Full functionality |
| Branching | Lightweight, fast | Lightweight |
| Learning curve | Steep | Gentle |
| Adoption | Dominant | Niche usage |
When to choose — Git, thanks to its dominant ecosystem, hosting options and community support.
Git vs GitHub
Git is the version control tool that runs on your machine; GitHub is a hosting platform built around it. They solve different problems: Git tracks history, GitHub adds collaboration - pull requests, issues, permissions and CI. GitLab and Bitbucket play the same role.
| Criterion | Git | GitHub |
|---|---|---|
| What it is | Version control software (CLI/tool) | Cloud platform hosting Git repositories |
| Runs | Locally, offline | As a web service |
| Account required | No | Yes |
| Collaboration features | None built in (push/pull only) | Pull requests, issues, code review, CI/CD |
When to choose — Not either/or: most teams use Git locally with a hosting platform on top. Git alone is enough for solo, offline or self-hosted work.
Myths, corrected
Myth
Git and GitHub are the same thing.
Correction
Git is the version control system - the software that tracks changes in your files. GitHub is a web-based platform that hosts Git repositories and adds features like issue tracking, pull requests and project management. You can use Git without GitHub, and GitHub is one of several hosts (alongside GitLab and Bitbucket).
Why it happens: Most people first encounter Git through GitHub, so the tool and the platform get conflated.
Myth
Git stores only the differences between file versions.
Correction
Each commit records the complete state of the project at that point in time, referenced by content hashes - Git optimizes storage internally, but conceptually it stores snapshots, not diffs.
Why it happens: Older version control systems were diff-based, so people assume Git works the same way.
Myth
Deleting your local repository means losing your work.
Correction
If your commits were pushed to a remote, cloning again restores everything - the deleted folder was never the only copy. Only local commits that had not been pushed are actually at risk.
Why it happens: In centralized systems, the local copy feels expendable and the server is the single source of truth.
Practical implications
For admins
Sysadmins can version-control configuration files, deployment scripts and infrastructure-as-code (Ansible, Terraform, Kubernetes manifests) with the same rigor as application code, and use .gitignore to exclude sensitive files and artifacts.
For MSPs
MSPs can standardize client environments on Git-backed configuration and maintain remote mirrors across multiple platforms for redundancy.
For business
Git enables reliable collaboration, auditability and faster delivery, and underpins CI/CD and DevOps practices that shorten release cycles.
For security
Because every object is content-addressed, tampering is detectable, and pre-commit hooks can run formatting, testing and security scanning. Keep secrets out from the start with .gitignore and secret scanning - removing them after a commit requires rewriting history.
For end users
For non-developers such as technical writers, Git provides versioned collaboration on text-based content with the ability to revert changes.
Cost impact
Git itself is free and open source; costs arise mainly from hosting plans, storage (especially with Git LFS) and training.
Operational impact
Adopting branching strategies and commit conventions improves traceability but requires team discipline and onboarding.
Decision guide
Use when
- You need to track changes in source code or text-based files over time.
- Multiple people collaborate on the same project.
- You want offline version control and full local history.
- You manage infrastructure-as-code or configuration that needs auditability.
Avoid when
- Your project is dominated by very large binary assets and you cannot use Git LFS.
- You need a strictly centralized model with minimal history replication and no team appetite for Git's learning curve.
Requirements
- Git installed locally on each machine.
- A remote repository (self-hosted or on GitHub/GitLab/Bitbucket) for collaboration and backup.
- Basic familiarity with add, commit, push and pull.
Alternatives
- Subversion (SVN) for centralized legacy workflows.
- Mercurial for a distributed model with a gentler learning curve.
Related terms
Distributed version control system (DVCS)
The tool family Git belongs to, alongside Mercurial and Fossil - as opposed to centralized systems like SVN, where the server holds the only complete history.
Both noun and verb: "to commit" records the staged changes; "a commit" is the resulting snapshot, usually referenced by its 7-character short hash (e.g. a1b2c3d).
Branch
Branches are local by default in Git - one exists on the remote only once pushed, a frequent surprise for users coming from centralized tools.
Merge conflict
A situation where competing changes to the same content require manual resolution.
Git LFS
Git Large File Storage, an extension for versioning large binary files.
Pull request
A request to review and merge changes from one branch into another, common in Git hosting platforms.
Frequently asked questions
What is Git used for?
Git is primarily used for tracking changes in source code during software development. It is also used for managing documentation, configuration files and infrastructure-as-code, research datasets and scripts, and any text-based content that needs version control and collaboration features.
Is Git the same as GitHub?
No. Git is the tool on your machine and needs no account or platform to work - even a bare folder on a NAS can act as a remote. GitHub, GitLab and Bitbucket host repositories and layer collaboration on top: pull requests, issues, permissions and CI.
How do I get started with Git?
Install Git on your computer, then learn the basic commands: git init to create a repository, git add to stage changes, git commit to save a snapshot, and git push to upload to a remote. Practice with a simple project, then learn branching and how to undo a commit safely.
What happens if I delete my local Git repository?
Clone the remote again and you are back to your last push. The real risk is work that was committed locally but never pushed - it lived only in that deleted folder. Make pushing (or adding a second remote) a daily habit.
How does Git store project history?
Through a content-addressed object database: each commit references a full tree of the project, and every object is named by its hash (SHA-1, moving to SHA-256). Identical content is stored only once, which keeps snapshots compact - and any corruption changes a hash, so it is detected immediately.
Conclusion
This article walked through Git's snapshot model, the working directory to staging to repository to remote workflow, its distributed architecture, and the trade-offs that come with it - from binary-file bloat to the learning curve of history rewriting.
The practical rule of thumb: commit small and often, branch freely, and treat every clone as both a workspace and a backup. Pair Git with a hosting platform such as GitHub or GitLab when you need code review, permissions and CI - and reach for Git LFS or a centralized system only when huge binary assets or strict locking dominate your workflow.
Main takeaway
Once you are comfortable with add, commit and push, explore branching strategies (Git Flow, GitHub Flow), rebasing, cherry-picking, Git hooks and Git LFS.