What Is Monitoring? Definition, How It Works, and Use Cases

- Level
- Beginner
- Reading time
- 9 min
- Concept
- IT Monitoring
- Last reviewed
- July 23, 2026
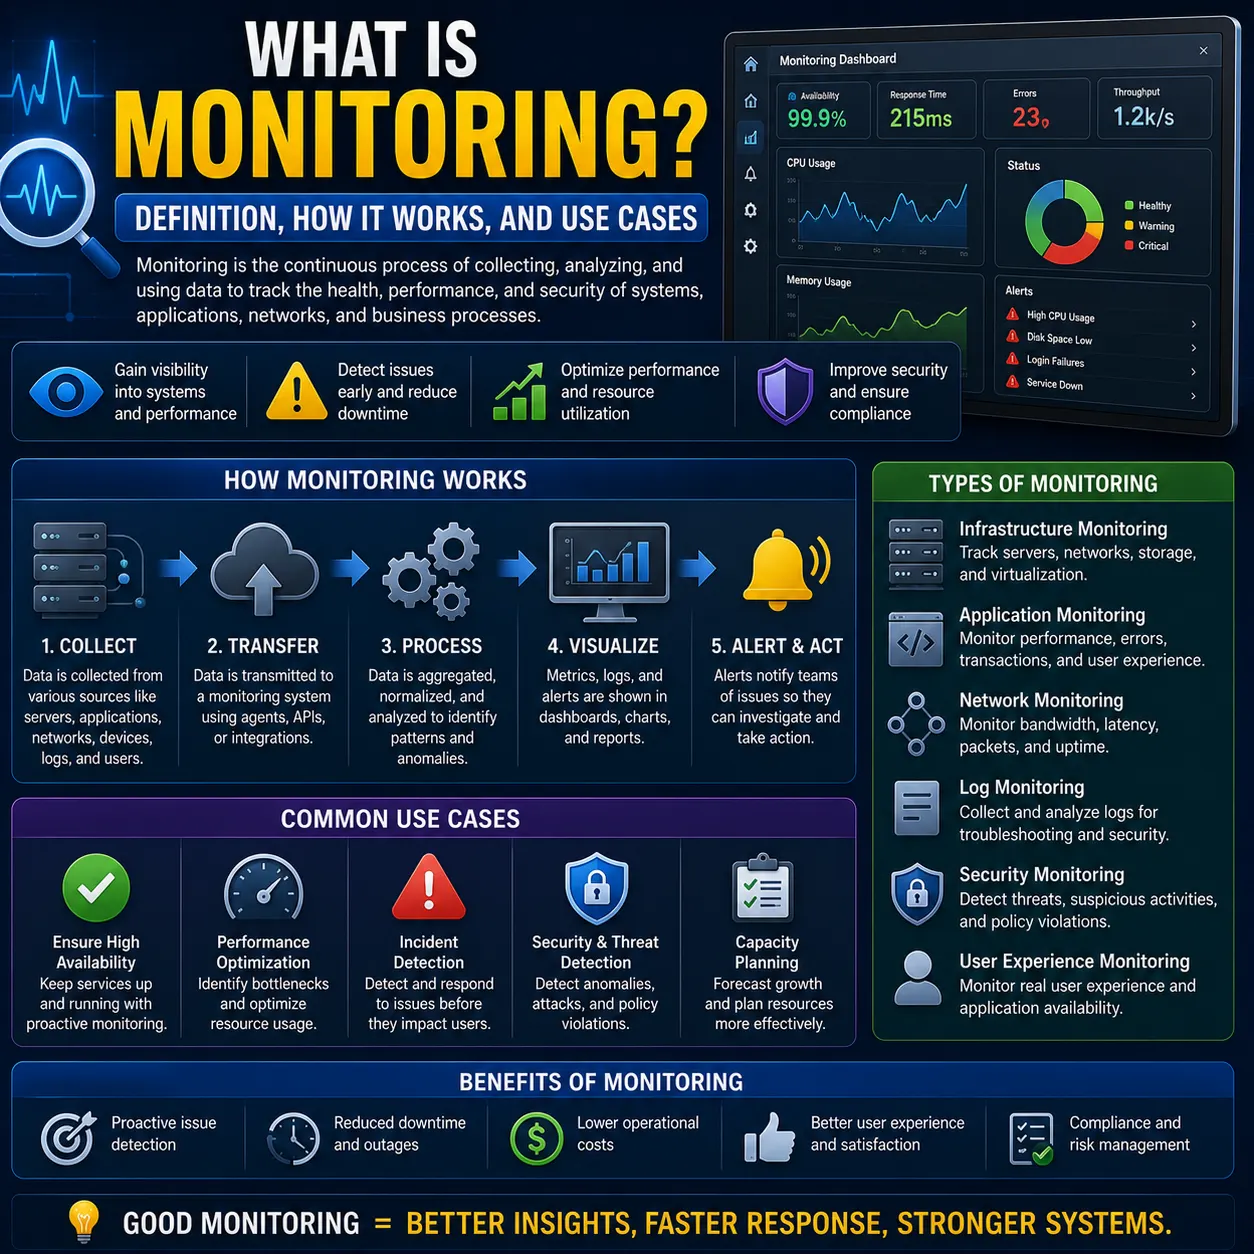
Table of contents
IT monitoring is the continuous observation of systems, applications, and infrastructure to maintain performance, availability, and security. It combines real-time data collection from agents and APIs, threshold-based alerting, and dashboard visualization to give IT teams actionable visibility.
Key takeaways
- Monitoring continuously collects, analyzes, and alerts on system metrics to ensure availability and performance.
- The four golden signals (latency, traffic, errors, saturation) are the core metrics framework.
- Data flows through five stages: collection, processing, analysis, alerting, visualization.
- Monitoring tracks known metrics and alerts on thresholds. Observability enables exploration of unknown problems.
- Alert fatigue from poorly configured thresholds is the most common deployment pitfall.
Quick explanation
In simple terms
IT monitoring continuously watches your systems to make sure they work properly and alerts you when something goes wrong or is about to.
Technical definition
Monitoring is the systematic collection of time-series metrics, logs, and traces from infrastructure and applications via agents, agentless protocols (SNMP, WMI, APIs), or synthetic probes. Data is stored in time-series databases, analyzed against thresholds and anomaly models, and surfaced through dashboards and alert pipelines.
Analogy
Monitoring is like a hospital vital signs display. Medical equipment tracks heart rate, blood pressure, and oxygen levels and sounds alarms when values leave safe ranges. IT monitoring tracks CPU, memory, response times, and error rates, alerting your team when something needs attention.
Definition
IT monitoring is the continuous tracking of system performance, availability, and health through real-time data collection, threshold-based alerting, and dashboard visualization.
Why it matters
Core concepts
The Four Golden Signals
The four golden signals are latency, traffic, errors, and saturation, a framework for the core metrics every system should track.
Popularized by Google's SRE book, the four golden signals cover the essential dimensions of system health. Latency measures how long requests take. Traffic measures demand volume. Errors measure the failure rate. Saturation measures how close to capacity the system is. Together they answer: is the system fast, busy, broken, or full? Starting with these four avoids the common pitfall of monitoring too many low-value metrics.
Example
A web API team monitors: latency (p95 response time 200ms), traffic (1,200 req/s), errors (0.3% 5xx rate), saturation (CPU at 65%, memory at 72%). An alert fires when p95 latency exceeds 500ms or error rate crosses 1%.
Why it matters — Focusing on four signals instead of hundreds of metrics prevents alert fatigue and ensures you catch the problems that actually affect users.
The Monitoring Pipeline: From Collection to Dashboard
The monitoring pipeline is the five-stage process that turns raw system data into actionable alerts and dashboards.
Stage 1: Collection via agents (Prometheus exporters, Datadog Agent), agentless protocols (SNMP, WMI), synthetic probes (HTTP checks), or log shipping (Fluentd, Logstash). Stage 2: Processing and storage in time-series databases optimized for high-volume timestamped data. Stage 3: Analysis using static thresholds, anomaly detection, or ML-based pattern recognition. Stage 4: Alerting through integrations like PagerDuty, Slack, email, or webhooks, with grouping and suppression to reduce noise. Stage 5: Visualization via dashboards tailored for operators, managers, and executives.
Example
A Prometheus agent scrapes CPU metrics from a server every 15 seconds (collection). InfluxDB stores the time-series data (processing). A Grafana alert rule checks if CPU exceeds 90% for 5 minutes (analysis). PagerDuty pages the on-call engineer (alerting). The Grafana dashboard shows the CPU spike in context with memory, disk, and network (visualization).
Why it matters — Understanding the pipeline helps you diagnose monitoring gaps: are you collecting the right data, storing enough history, alerting the right people, and showing the right dashboards?
Monitoring vs Observability
Monitoring tracks known metrics and alerts on thresholds. Observability enables exploration of unknown problems through metrics, logs, traces, and contextual metadata.
Monitoring answers 'is it broken?' by checking predefined conditions. Observability answers 'why is it broken?' by enabling ad-hoc exploration of system internals. Monitoring relies on dashboards and alerts. Observability relies on query tools (Jaeger for traces, Loki for logs, PromQL for metrics) that let engineers ask questions they didn't anticipate. Most organizations need both: monitoring for operational alerting on known failure modes, and observability for troubleshooting complex, distributed, emergent issues.
Example
Monitoring catches: disk space dropped below 10% (known threshold). Observability catches: a specific microservice is slow, but only for users in one region, only on requests that hit a particular database shard, during a 20-minute window. You discover this by querying distributed traces, not by a predefined alert.
Why it matters — Choosing the right approach depends on your architecture. Traditional infra needs monitoring. Microservices and cloud-native systems need observability. Most hybrid environments need both.
Benefits
Proactive problem detection
Monitoring catches problems before users notice them, reducing downtime from hours to minutes.
A disk space alert at 85% gives the team time to clean up or expand storage before the database crashes at 100%.
Data-driven capacity planning
Historical monitoring data shows usage trends, enabling accurate capacity planning and cost optimization.
Six months of CPU and memory data shows the web tier needs scaling in Q4 but is overprovisioned in Q1, saving cloud spend.
Compliance and audit readiness
Continuous monitoring provides the audit trails required by SOX, HIPAA, PCI-DSS, and ISO 27001.
A PCI-DSS auditor requests proof that all database access is logged and monitored. The SIEM dashboard and alert history satisfy the requirement.
Limitations
Alert fatigue
HighPoorly tuned thresholds and excessive alerting desensitize teams, causing them to ignore or dismiss genuine alerts.
Workaround — Start with the four golden signals. Use alert grouping, escalation policies, and maintenance windows. Review alert accuracy quarterly.
Resource overhead from monitoring infrastructure
MediumMonitoring agents, log shippers, and time-series databases consume CPU, memory, disk, and network bandwidth on the systems they monitor.
Workaround — Use lightweight agents. Tune collection intervals (15-60s for most metrics). Archive old data to cheaper storage tiers.
Monitoring alone can't explain root causes
MediumMonitoring tells you something is wrong but not necessarily why. Complex distributed systems need observability (traces, contextual queries) to diagnose root causes.
Workaround — Complement monitoring with distributed tracing (Jaeger, Zipkin) and log querying (Loki, Elasticsearch) for root cause analysis.
Myths, corrected
Myth
More metrics means better monitoring
Correction
Tracking hundreds of low-value metrics creates noise and alert fatigue. The four golden signals (latency, traffic, errors, saturation) cover most use cases. Add metrics only when they're tied to specific SLOs or troubleshooting needs.
Why it happens: Monitoring tools make it easy to collect everything. Teams enable all available metrics without asking which ones drive action.
Myth
Monitoring and observability are the same thing
Correction
Monitoring tracks known metrics with predefined alerts (is it broken?). Observability enables ad-hoc exploration of unknown problems (why is it broken?). They're complementary, not interchangeable. Traditional infrastructure needs monitoring; complex distributed systems also need observability.
Why it happens: Vendors market observability platforms as monitoring replacements. The terms are used interchangeably in marketing.
Myth
Setting up monitoring is a one-time project
Correction
Monitoring requires ongoing tuning: adjusting thresholds as baselines shift, adding coverage for new services, removing stale alerts, and reviewing effectiveness after incidents. Treat it as a continuous practice, not a deployment.
Why it happens: Teams install a tool, configure initial dashboards, and move on. Alert accuracy degrades over time as systems change.
Practical implications
For admins
Start with the four golden signals on your most critical systems. Use Prometheus + Grafana or your cloud provider's native monitoring. Set actionable thresholds tied to SLOs, not arbitrary percentages. Review and tune alerts quarterly.
For MSPs
Standardize monitoring across clients using a common platform (Datadog, Zabbix, or cloud-native tools). Build templated dashboards and alert profiles per workload type. Alert fatigue is your biggest operational risk, tune aggressively.
For business
Monitoring directly reduces downtime costs and supports SLA commitments. Budget for ongoing tuning, not just initial deployment. The ROI comes from prevented outages and faster incident resolution.
For security
Integrate monitoring with SIEM for security event correlation. Monitor authentication failures (Event 4625), privilege changes, and network anomalies. Use monitoring baselines to detect deviations that indicate compromise.
Frequently asked questions
What is monitoring in simple terms?
IT monitoring is the continuous tracking of systems, applications, and infrastructure to ensure they perform correctly. It collects metrics like CPU usage, response times, and error rates, compares them to thresholds, and alerts teams when issues arise.
What are the most important metrics to monitor?
Focus on the four golden signals from Google SRE: latency (response time), traffic (request volume), errors (failure rate), and saturation (resource utilization like CPU and memory). These cover the essential dimensions of system health.
Is monitoring the same as observability?
No. Monitoring tracks known metrics and alerts on thresholds. Observability enables exploration of unknown problems through metrics, logs, traces, and contextual queries. Most organizations need both: monitoring for alerting, observability for root cause analysis.
How do I get started with monitoring?
Identify your most critical systems and define success metrics (uptime, response time targets). Choose a monitoring tool (Prometheus/Grafana for open source, Datadog or Azure Monitor for managed). Implement basic health checks and alerts on the four golden signals. Expand coverage gradually.
How do I avoid alert fatigue?
Start with the four golden signals instead of monitoring everything. Use alert grouping and escalation to reduce noise. Set thresholds based on business impact, not arbitrary numbers. Review alert accuracy quarterly and remove stale or low-value alerts.
What are common monitoring tools?
Popular tools include Prometheus + Grafana (open source), Datadog, New Relic, and Dynatrace (SaaS), Zabbix and Nagios (traditional open source), Azure Monitor and AWS CloudWatch (cloud-native), and SCOM (Microsoft enterprise). Choice depends on environment, budget, and scale.
Conclusion
IT monitoring continuously tracks system performance, availability, and health through a five-stage pipeline: collection, processing, analysis, alerting, and visualization. The four golden signals (latency, traffic, errors, saturation) provide a proven starting framework. Monitoring and observability are complementary: monitoring alerts on known conditions, observability helps diagnose unknown problems. Alert fatigue is the biggest pitfall, solved by focusing on business-impact thresholds and quarterly review.
Main takeaway
Look into observability (OpenTelemetry, distributed tracing), SRE practices (SLIs, SLOs, error budgets), and specific tools like Prometheus, Grafana, Datadog, or Azure Monitor for implementation.