What is SLA? Definition, How It Works & Use Cases

- Level
- Beginner
- Reading time
- 23 min
- Concept
- SLA (Service Level Agreement)
- Last reviewed
- July 5, 2026
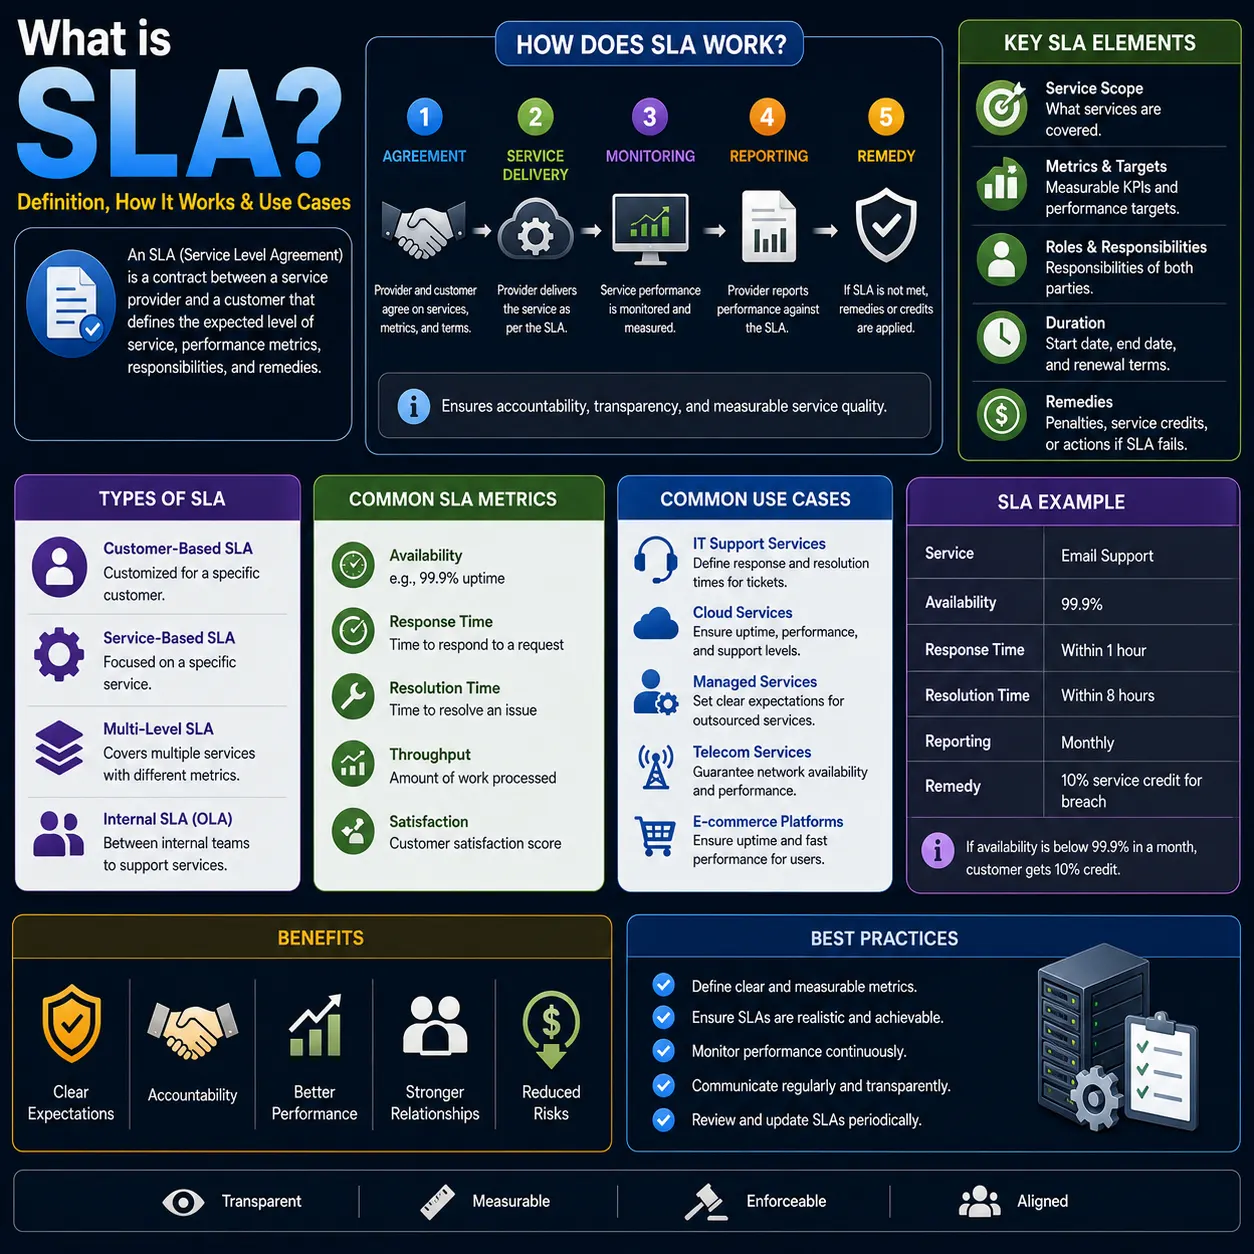
Table of contents
Your e-commerce platform goes down for three hours on Black Friday, costing a fortune in lost sales. You call the provider, and they calmly point to the SLA: 99.9% uptime - which technically permits about 8.76 hours of downtime a year. You're owed a service credit worth a fraction of what you lost. That gap is the whole point of understanding SLAs. They're not a promise that nothing breaks; they're a measurable commitment about how much can break, how it's counted, and what you get when it does. Whether you buy services or deliver them, reading an SLA precisely - targets, measurement window, remedies, and especially exclusions - is what keeps expectations and reality aligned.
Key takeaways
- An SLA is a contract that defines committed service levels, how they're measured, and the remedies for missing them.
- Availability is stated in 'nines': 99.9% still allows ~8.76 hours of downtime a year, and each extra nine is ~10x harder.
- SLA (external contract) sits above SLOs (internal targets) and SLIs (raw measurements); SLOs are set tighter for a buffer.
- Remedies are usually service credits worth 10-30% of the monthly fee - rarely enough to cover the actual business loss.
- Exclusions and the measurement window (monthly vs annual, planned maintenance, force majeure) decide what really counts as a breach.
Quick explanation
In simple terms
An SLA is a promise with consequences: a provider commits to a level of service, and if they don't meet it, the customer is owed something - usually a credit.
Technical definition
A formal service commitment defining scope, quantitative targets (availability, response/resolution times, performance), measurement methodology and window, remedies for non-conformance, and exclusions - distinct from the SLOs (internal targets) and SLIs (measurements) that underpin it.
Analogy
Think of an SLA like a delivery guarantee: the courier promises next-day delivery and refunds the shipping fee if they're late. The refund (the credit) rarely covers the value of what was in the box - which is exactly why the guarantee isn't a substitute for planning.
Definition
An SLA is a formal agreement between a service provider and a customer that defines the level of service to be delivered - the specific metrics, how they're measured, and the remedies that apply when targets are missed. It's a measurable commitment with consequences, not a guarantee of perfection.
A Service Level Agreement (SLA) is a documented agreement that defines the service a provider commits to deliver and what happens if it falls short. It turns vague promises like 'highly available' into measurable, enforceable terms.
A usable SLA specifies several things: the scope (which services and components are covered), the metrics and targets (for example 99.9% monthly uptime, a 15-minute response time, a 4-hour resolution time for critical incidents), the measurement method and window (how 'downtime' is defined and whether it's measured monthly or annually), the remedies (usually service credits) when targets are missed, and the exclusions (planned maintenance, force majeure, customer-caused issues) that don't count against the targets.
Crucially, an SLA is the external, contractual layer. Internally, teams track Service Level Indicators (SLIs) - the raw measurements - against Service Level Objectives (SLOs) - internal targets that are usually set tighter than the SLA to leave a safety buffer. Getting these distinctions right is what separates a well-run service commitment from a nasty surprise during an outage.
Why it matters
Core concepts
The anatomy of an SLA
A usable SLA has a fixed set of parts that together make it measurable and enforceable.
Every solid SLA defines: scope (which services and components are covered); metrics and targets (uptime %, response and resolution times, performance thresholds); the measurement method and window (how downtime is defined, and whether it's tracked monthly or annually); responsibilities and escalation (who does what, and how issues escalate); remedies (service credits or penalties when targets are missed); and exclusions (what doesn't count, such as maintenance). Missing any of these turns the agreement into a source of disputes rather than clarity.
Example
An MSP SLA might promise 99.9% monthly uptime, 15-minute acknowledgement and 4-hour resolution for critical tickets, measured by an independent monitor, with a 10% monthly-fee credit per breach and planned maintenance excluded.
Why it matters — The parts a reader skips - usually measurement window and exclusions - are the ones that decide whether a real outage counts as a breach.
Availability and the 'nines'
Uptime commitments are expressed as a percentage, popularly counted in 'nines', each mapping to an allowed amount of downtime.
Availability is a percentage of a time window, and each extra nine cuts allowed downtime tenfold:
- 99% (two nines): ~3.65 days/year (~7.2 hours/month)
- 99.9% (three nines): ~8.76 hours/year (~43.8 minutes/month) - the common SaaS baseline
- 99.95%: ~4.38 hours/year (~21.9 minutes/month)
- 99.99% (four nines): ~52.6 minutes/year (~4.38 minutes/month)
- 99.999% (five nines): ~5.26 minutes/year (~26 seconds/month)
Each additional nine is roughly 10x more expensive and harder to achieve, demanding automated failover, multi-region redundancy, and detection in seconds. Most businesses don't need beyond four nines.
Example
A '99.9% uptime' guarantee sounds airtight but still allows nearly nine hours of downtime a year - one bad incident can consume a whole month's budget.
Why it matters — Translating a percentage into real minutes is what turns a marketing number into an honest expectation.
SLA vs SLO vs SLI
Three layers of the same idea: measurement, internal target, and external commitment.
An SLI (Service Level Indicator) is the raw measurement - for example the percentage of successful requests. An SLO (Service Level Objective) is the internal target for that indicator - say 99.95% - that engineering teams operate against. An SLA (Service Level Agreement) is the external, contractual commitment, usually set a notch more conservative than the SLO so there's a buffer before penalties apply. The related idea of an error budget flips the SLO around: if your SLO is 99.9% monthly, you have about 43 minutes of 'budget' to spend on incidents and risky changes before you must shift focus to reliability.
Example
SLI: 99.97% successful requests measured. SLO: 99.95% internal target. SLA: 99.9% promised to customers, with credits below that.
Why it matters — Conflating these leads teams to expose their internal target as a contractual promise, removing the buffer that protects them from penalties.
OLAs and underpinning contracts
The internal and supplier agreements that make a customer-facing SLA achievable.
In ITIL/ITSM terms, an Operational Level Agreement (OLA) is an *internal* agreement between teams within the same organization (for example, the network team commits to restore connectivity within an hour to support the customer SLA). An Underpinning Contract (UC) is an agreement with an *external* supplier that the provider depends on. Both must be at least as strict as the customer SLA - if an internal team or upstream vendor can only commit to a weaker target, the SLA can't reliably be met.
Example
A 4-hour customer resolution SLA is backed by an OLA where the infrastructure team commits to 2-hour escalation handling, and a UC where the datacenter vendor guarantees rapid hands-on support.
Why it matters — SLAs fail quietly when the internal OLAs and supplier UCs behind them are weaker than the promise made to the customer.
Service credits and remedies
The compensation a customer receives when the provider misses SLA targets.
The most common remedy is a service credit - a percentage of the monthly fee applied against a future invoice, typically 10-30% per breach and often tiered by how far below target the service fell. Credits are usually capped (frequently at the monthly fee) and are the customer's exclusive remedy. That means they almost never cover the real business impact of an outage - lost revenue, reputational damage, or downstream costs - which is why credits should be treated as a floor, not protection.
Example
A 99.9% SLA might grant a 10% credit for 99.0-99.9% uptime and 25% below 99.0%, capped at that month's fee.
Why it matters — Assuming credits make you whole after an outage is a costly misread; they're a modest, capped incentive for the provider, not insurance for the customer.
Exclusions and the measurement window
The rules that determine what actually counts as downtime - and therefore as a breach.
SLAs carve out exclusions: planned maintenance windows, force majeure, third-party failures, and customer-caused issues typically don't count against the target. Equally important is the measurement window and method: monthly windows reset the budget each billing cycle (so one bad month triggers a credit), while probe-based monitoring from the provider's vantage point can miss regional or partial outages that customers still feel. Reading these determines whether a real outage is a breach on paper.
Example
A four-hour outage during a declared maintenance window, or caused by an upstream provider explicitly excluded in the contract, may not count against the SLA at all.
Why it matters — Exclusions and measurement rules quietly swallow a large share of real-world downtime; they're where the actual protection is won or lost.
How it works
Define scope and covered services
The agreement first states exactly which services, systems, and components it covers, removing ambiguity about what's in and out of scope.
Scope
Example — The SLA covers the production web application and API, but not the customer's own network.
Set measurable targets and the measurement window
Quantifiable targets are agreed - uptime, response, resolution, performance - along with how each is measured and over what period (monthly or annual).
Metrics + window
Example — 99.9% monthly uptime and 4-hour critical resolution, measured by an agreed monitoring method.
Monitor and measure continuously
Automated monitoring records actual performance against the targets around the clock, creating the objective evidence used to judge compliance.
Monitor (SLIs)
Example — External probes and internal telemetry track uptime and ticket timers in real time.
Report and review on a cadence
Performance is reported against targets on a regular cycle, surfacing trends and recurring issues and feeding periodic SLA reviews.
Report + review
Example — A monthly service review compares measured uptime to the 99.9% commitment.
Apply remedies on breach
When a target is missed, the agreed remedies activate - service credits, escalation, and in serious cases termination rights - according to the contract.
Remedies
Example — Uptime of 99.4% in a month triggers the tiered service credit and a formal review.
Use cases
Cloud infrastructure and platform services
Cloud / infrastructure teamsHyperscalers commit to availability for compute, storage, and platform services, with credits when monthly uptime falls below target.
Provider compute SLAs commonly sit around 99.95-99.99% monthly uptime, with tiered credits below that (always check the current, service-specific terms).
Benefit — A defined baseline and recourse for cloud-hosted workloads.
Managed service provider contracts
MSPs and their clientsMSPs commit to monitoring, response, and resolution targets for outsourced IT, protecting the client while giving the provider clear goals.
Monitoring, patching, backup, and security services with response/resolution SLAs and monthly reporting.
Benefit — Accountability and clear performance targets for outsourced IT.
SaaS application commitments
Business / IT buyersSaaS vendors publish availability SLAs, sometimes tiered by plan, to assure customers about uptime.
A vendor guaranteeing 99.9% availability with service credits for shortfalls.
Benefit — Confidence and recourse for business-critical SaaS.
Internal IT / ITSM
Internal IT / ITSMIT departments formalize service delivery to internal business units, backed by OLAs between supporting teams.
Help desk acknowledgement in 15 minutes and 4-hour critical resolution, underpinned by an infrastructure-team OLA.
Benefit — Accountability that demonstrates IT's value internally.
Telecom and network services
Network / enterprise buyersISPs and carriers guarantee availability, latency, and packet-loss thresholds, often with custom enterprise terms.
A dedicated business circuit with an availability SLA and latency ceiling.
Benefit — Predictable connectivity for business continuity.
Benefits
Clear, measurable expectations
SLAs replace vague promises with specific targets both sides understand and can verify.
'Highly available' becomes '99.9% monthly uptime, measured this way.'
Accountability and recourse
Defined remedies give customers something concrete when targets are missed and hold providers to their word.
A breach automatically triggers the agreed service credit.
Risk allocation
SLAs make explicit who bears the consequences of failures and to what extent.
Exclusions and credit caps define the boundaries of each party's exposure.
Drives investment in reliability
The prospect of penalties motivates providers to build redundancy, monitoring, and process maturity.
Committing to four nines forces automated failover and fast detection.
Competitive differentiation
Stronger, clearer SLA terms can win reliability-sensitive customers.
A provider marketing a higher availability tier at a premium price.
Limitations
Credits rarely cover real losses
HighRemedies are typically a capped 10-30% of the monthly fee - far below the true cost of a serious outage.
Workaround — Treat credits as a floor; invest in your own redundancy, backups, and DR for the losses credits won't cover.
Exclusions swallow real downtime
HighPlanned maintenance, force majeure, and third-party failures often don't count, so 'met' SLAs can coexist with painful outages.
Workaround — Read exclusions before signing; negotiate narrower carve-outs for business-critical services.
The watermelon effect
MediumAn SLA can look green on the metrics while users experience red - the tracked number misses partial failures, latency, or regional issues.
Workaround — Measure the real user experience independently; consider experience-level metrics (XLAs) alongside the SLA.
False sense of security
MediumOrganizations over-rely on SLA protections instead of building their own resilience.
Workaround — Pair every critical SLA with independent monitoring and a tested continuity plan.
Measurement disputes and gaming
MediumAmbiguous definitions cause arguments over whether a target was met, and providers may optimize the metric rather than the experience.
Workaround — Define measurement method, window, and vantage point precisely, ideally with independent monitoring.
Administrative overhead
LowTracking, reporting, and enforcing SLA compliance takes tooling and staff time on both sides.
Workaround — Automate SLI collection and SLA reporting to keep the overhead manageable.
Architecture
Structurally, an SLA is a document with interlocking parts: scope, metrics and targets, measurement method and window, responsibilities and escalation, remedies, exclusions, and a review cadence. Behind it sit the internal OLAs and supplier underpinning contracts that make the external promise deliverable, and the SLIs/SLOs the provider operates against day to day.
Scope statement
Defines exactly which services and components are covered.
Production app and API, excluding customer LAN.
Metrics and targets
The measurable commitments (uptime, response, resolution, performance).
99.9% uptime; 4-hour critical resolution.
Measurement method and window
How each metric is measured and over what period.
Independent monitoring, monthly window.
Remedies
Compensation when targets are missed, usually service credits.
10-30% monthly-fee credit, tiered and capped.
Exclusions
What doesn't count against the targets.
Planned maintenance, force majeure, third-party outages.
OLAs and underpinning contracts
Internal and supplier agreements that back the customer SLA.
Network team OLA; datacenter vendor UC.
Data flow
SLIs measured by monitoring feed comparison against SLOs (internal) and the SLA (external). Reporting on a cadence documents compliance; a breach against the SLA target triggers the defined remedies. OLAs and underpinning contracts must meet or exceed the SLA's targets for the chain to hold.
Integrations: Uptime and APM monitoring (SLI collection), ITSM/ticketing for response and resolution timers, Status pages and SLA reporting dashboards
Architecture limitations
Examples
Reading the nines correctly
A buyer sees '99.9% uptime' and assumes near-perfect availability.
99.9% over a monthly window allows about 43.8 minutes of downtime a month (roughly 8.76 hours a year). A single multi-hour incident breaches it, while several short blips can too.
The Black Friday credit gap
A three-hour outage during peak sales costs a retailer heavily.
The provider's 99.9% SLA was still technically met for the month, or the breach only entitled the retailer to a credit worth a fraction of the monthly fee - nowhere near the lost revenue.
An OLA that backs the SLA
An MSP promises 4-hour critical resolution to a client.
To keep that promise, the MSP's internal OLA commits the infrastructure team to a 2-hour escalation response, and an underpinning contract secures rapid datacenter support - each stricter than the customer SLA.
Comparisons
SLA vs SLO vs SLI vs SLO and SLI
Three layers of the same reliability idea: SLIs measure, SLOs target internally, SLAs commit externally.
| Criterion | SLA vs SLO vs SLI | SLO and SLI |
|---|---|---|
| What it is | External contractual commitment | SLO: internal target · SLI: raw measurement |
| Audience | Customers, legal, procurement | Engineering and operations teams |
| Consequence of missing | Service credits or penalties | Internal escalation / reliability work; none directly for an SLI |
| Typical strictness | Looser than the SLO (safety buffer) | SLO set tighter than the SLA |
When to choose — Operate to SLOs and SLIs internally; commit to a slightly looser SLA externally.
SLA vs OLA vs Underpinning Contract vs OLA and Underpinning Contract
An SLA faces the customer; OLAs and underpinning contracts are the internal and supplier agreements that make it deliverable.
| Criterion | SLA vs OLA vs Underpinning Contract | OLA and Underpinning Contract |
|---|---|---|
| Parties | Provider ↔ customer | OLA: internal teams · UC: provider ↔ external supplier |
| Direction | External-facing | Internal / supply-chain-facing |
| Required strictness | The promise to meet | Must be at least as strict as the SLA |
When to choose — Back every customer SLA with OLAs and UCs that are equal to or stricter than it.
Myths, corrected
Myth
An SLA guarantees my service won't go down.
Correction
An SLA defines a target and a remedy, not a guarantee. A 99.9% SLA explicitly permits about 8.76 hours of downtime a year; it promises compensation, not perfection.
Why it happens: High percentages read as 'basically always up,' hiding how much downtime they actually allow.
Myth
SLA credits will compensate my outage losses.
Correction
Credits are typically a capped 10-30% of the monthly fee and are usually the exclusive remedy - rarely close to the real revenue or reputational loss from an outage.
Why it happens: People assume a 'penalty' equals being made whole, rather than a modest capped incentive.
Myth
SLA and SLO are the same thing.
Correction
An SLA is the external contract with consequences; an SLO is an internal target, usually set tighter to give a buffer before the SLA is breached.
Why it happens: The acronyms are similar and both are stated as percentages.
Myth
A higher uptime percentage is always better.
Correction
Each additional nine costs roughly 10x more to achieve. Beyond four nines is unjustified for most services, and paying for five nines you don't need is wasted money.
Why it happens: More nines sound more reliable, so bigger seems automatically better.
Myth
If the status page is green, the SLA was met and all is well.
Correction
Provider probes can miss regional or partial outages, and exclusions can remove real downtime from the count - the 'watermelon effect' where metrics look green while users see red.
Why it happens: Teams trust the provider's own vantage point instead of measuring the actual user experience.
Practical implications
For admins
When buying, read the measurement window, exclusions, and remedy caps before the uptime number; when providing, set your SLO tighter than the SLA and instrument SLIs so you can prove compliance and catch breaches early.
For MSPs
You sit on both sides: honor client SLAs with realistic targets and stricter internal OLAs, and hold your own suppliers to underpinning contracts at least as strict as what you promise clients. Independent monitoring protects you in disputes.
For business
SLAs allocate risk but don't eliminate it; budget for the outage losses credits won't cover, and match availability tiers (and their cost) to how critical each service actually is.
For security
SLAs also cover incident response and security services - response and resolution times for incidents sit alongside availability, and should align with RTO/RPO targets in your continuity plan.
For end users
SLAs are invisible day to day but shape how quickly issues get fixed and what the business is owed when a service they rely on fails.
Cost impact
Reliability is priced in nines: each extra nine multiplies infrastructure and operational cost, so the goal is the right tier per service, not the highest number available.
Operational impact
Meeting an SLA is an operational program - monitoring, on-call, reporting, and reviews - not just a clause; the tighter the target, the more automation and redundancy it demands.
Decision guide
Use when
- Procuring or delivering cloud, SaaS, MSP, or telecom services that need accountability
- You need defined recourse and clear expectations between provider and customer
- Pricing service tiers against reliability commitments
Avoid when
- You're treating the SLA as a substitute for your own redundancy and DR
- You're paying for more nines than the service's criticality justifies
- The metric can't be measured objectively, inviting disputes
Requirements
- Objectively measurable metrics and an agreed measurement method and window
- Internal SLOs set tighter than the SLA, plus OLAs and supplier contracts to back it
- Monitoring and reporting to evidence compliance and detect breaches
Alternatives
- Internal SLOs and error budgets for engineering-driven reliability
- Experience-Level Agreements (XLAs) to capture real user experience
- Independent redundancy, backups, and DR for losses credits won't cover
Related terms
SLO (Service Level Objective)
An internal target for a service metric, usually set tighter than the SLA.
SLI (Service Level Indicator)
The raw quantitative measurement of service performance.
OLA (Operational Level Agreement)
An internal agreement between teams that supports a customer-facing SLA.
Underpinning Contract (UC)
An agreement with an external supplier that a provider depends on to meet its SLA.
Error budget
The allowed downtime implied by an SLO (100% minus the SLO), spent on incidents and change.
Uptime / availability
The percentage of a time window a service is operational, often expressed in nines.
Service credit
A capped percentage of the fee refunded when SLA targets are missed.
MTTR
Mean time to recovery - the average time to restore service after an incident.
XLA (Experience-Level Agreement)
A commitment based on the real user experience rather than raw system metrics.
Frequently asked questions
What is an SLA in simple terms?
An SLA (Service Level Agreement) is a contract between a provider and a customer that defines the service to be delivered, the metrics it's measured by (like uptime and response times), and the remedies - usually service credits - if targets are missed. It's a promise with consequences, not a guarantee of perfection.
What does 99.9% uptime actually allow?
About 43.8 minutes of downtime per month, or roughly 8.76 hours per year. Each additional nine cuts that tenfold: 99.99% allows about 52.6 minutes a year, and 99.999% about 5.26 minutes a year.
What's the difference between SLA, SLO, and SLI?
An SLI is the raw measurement, an SLO is the internal target for that measurement, and an SLA is the external contractual commitment. SLAs are usually set a little looser than SLOs so there's a buffer before penalties apply.
What is the difference between an SLA and an OLA?
An SLA is an agreement with an external customer. An OLA (Operational Level Agreement) is an internal agreement between teams within the same organization that supports the SLA. There's also the underpinning contract, which is an agreement with an external supplier. OLAs and underpinning contracts must be at least as strict as the SLA.
Do SLA credits cover the cost of an outage?
Rarely. Service credits are typically a capped 10-30% of the monthly fee and are usually the exclusive remedy, so they seldom match the real revenue, reputational, or downstream losses. Treat them as a floor, not insurance.
What happens when an SLA is breached?
The agreed remedies activate - most often a service credit against a future invoice, plus escalation procedures and, for serious or repeated breaches, potential termination rights. The specifics depend entirely on what the contract defines.
Why do exclusions matter so much in an SLA?
Exclusions - planned maintenance, force majeure, third-party failures, customer-caused issues - define what doesn't count against the targets. They can remove a large share of real-world downtime from the calculation, so a met SLA can still coincide with outages users felt.
How is SLA compliance measured?
Through monitoring that tracks metrics like uptime and response/resolution times against the targets over the agreed window, producing reports that evidence compliance. Independent, multi-location monitoring is more trustworthy than a provider's own probes, which can miss regional or partial outages.
Conclusion
An SLA is a measurable service commitment: it defines scope, metrics, a measurement window, remedies, and exclusions, and it sits above the internal SLOs and SLIs a provider operates against, backed by OLAs and supplier contracts. Availability is stated in nines - 99.9% still allows nearly nine hours of downtime a year - and each extra nine is roughly ten times harder and costlier. The real skill is reading past the headline uptime to the measurement window, exclusions, and capped credits, because those decide what an SLA is actually worth when a service fails.
Main takeaway
Next, read an explainer on SLOs and error budgets for the engineering side, or a tutorial on setting up uptime monitoring to measure SLA compliance independently.